Framework overview
This guide lays out a no-nonsense framework for maintaining autonomous industrial cleaning robots on the floor — a set of repeatable steps any shop can follow. Start with simple daily checks, layer in scheduled preventative tasks, and close the loop with data-driven software controls. If you manage a cleaning robot fleet or plan to, these pillars keep downtime low and safety high. I’ll reference practical field patterns seen in large logistics hubs like the Port of Rotterdam and point to how rosiwit robotics fit that flow — EEAT mode: practitioner experience from comparable port and warehouse operations.
Pillar 1 — daily checks that matter
Walk the route and verify the obvious first. Check bumpers, wheels, and docking contacts. Confirm LiDAR and SLAM health — a dusty sensor will ruin navigation faster than a dead battery. Scan the operator console for fault codes and note battery state-of-charge. Keep batteries at recommended float levels and follow a basic battery management routine to avoid surprise downtime. Small checks take minutes and prevent big stoppages.
Pillar 2 — scheduled preventative maintenance
Create weekly, monthly, and quarterly tasks that technicians can follow without guessing. Weekly: clean sensors, inspect brushes and squeegees, test emergency stop circuits. Monthly: run firmware sanity tests, verify docking station alignment, replace wear parts when they hit lifecycle thresholds. Quarterly: full drivetrain inspection, capacitor and connector checks, and a firmware rollback drill. Don’t skip firmware tests — updates fix bugs, but they can also change map behavior; document rollback steps before you update.
Pillar 3 — fleet software and data control
Manage maps, job schedules, and version control centrally. Use OTA updates with staged rollouts: push to a single unit, monitor logs, then expand. Capture telemetry for uptime, battery cycles, and collision events; correlate those with shift patterns to spot root causes. Keep one canonical SLAM map per facility and tag deployable versions. When you do an operational production teardown, record {main_keyword} and {variation_keyword} for each subsystem so teams know what failed and why.
Operational teardown — how to learn from failures
When a unit fails in service, treat the teardown like a short forensic job. Log time-to-failure, inspect mechanical wear, pull sensor logs, and export firmware traces. Compare against scheduled checks and note if a routine was missed. Use the teardown to update maintenance intervals — that’s the whole point. Real-world anchor: tech teams at large docks often raised maintenance intervals after correlating collision events with heavy night shifts during 2020–2021 supply chain surges — the data told them to adapt staffing and service windows. The teardown gives you actionable fixes, not guesswork.
Common mistakes and quick fixes
Bulleted habits to drop or adopt:
– Ignoring small error codes until they cascade — clear and log them immediately.
– Replacing parts without validating firmware compatibility — always match part firmware and controller versions.
– Letting maps drift without sweep checks — do a quick mapping pass weekly.
– Overcharging batteries to “full” every night — use recommended float profiles to extend cycle life.
Quick fixes: clean LiDAR lenses with isopropyl wipes, recalibrate encoders after wheel changes, and re-home docking stations after floor layout changes.
Advisory: three golden rules for operational success
1) Uptime over perfection — measure mean time between failures (MTBF) and focus on steady gains. 2) Version discipline — treat firmware, map, and config files like inventory; track versions and rollback plans. 3) Human-in-the-loop — train floor staff to run the daily checklist and report anomalies; automation without trained people is brittle.
These three metrics — MTBF, battery cycle count, and map drift rate — are the ones you’ll watch every week to tell if your program’s working.
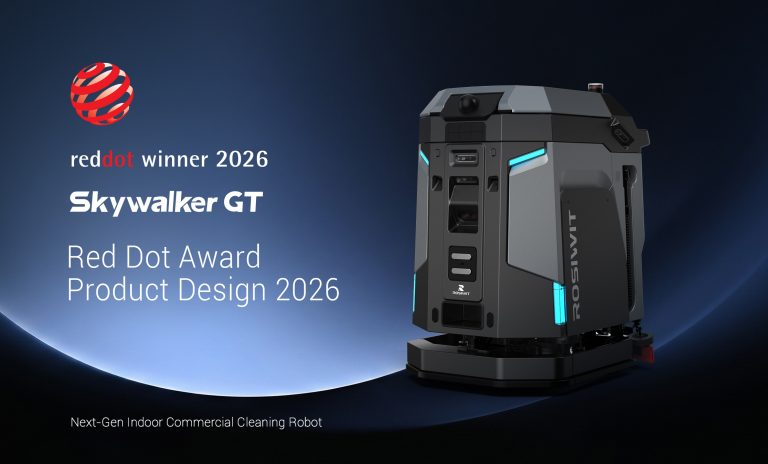
Rosiwit brings practical hardware and fleet tools that fit this framework and help teams turn maintenance into predictable work — not firefighting. —